Interactive Capabilities Lab

One Practice. Four Services.
Try Each One Below.

Explore the same open-source stack we deploy in production. Configure your appliance, run a workflow through the automation pipeline, and preview the live private AI demos. In your environment, everything runs on your own hardware — no public APIs, no per-token fees, zero data egress.

Service 01 · Private AI Deployment

Private AI Chat — ChatGPT-Class, On-Premises

Try it above — live, right now. Every user gets a familiar chat interface — model, memory, and data all stay in your network. This is the flagship of the deployment service: the same self-hosted Open WebUI + Ollama/vLLM stack, running on a server in your building.

Live demo — runs on an open-weight model (Qwen-7B). In production it runs on your own hardware; your data never leaves the building.

Workplace Use Cases

  • Drafting, summarizing, and proofreading — no client data sent to third parties
  • Staff copilot for SOPs, policies, and internal knowledge
  • A sanctioned alternative to shadow ChatGPT use
  • Role-scoped access with full audit logs

Technical Architecture

  • Frontend: Open WebUI (self-hosted, ChatGPT-class UX)
  • Engine: Ollama / SGLang / vLLM on 1–4 GPUs
  • Models: Qwen / DeepSeek / Llama-class open weights
  • Security: Firewall, fail2ban, encrypted VPN, verified zero egress
Client Value: ChatGPT-class capability with no per-token fees, no data leaving your walls, and no vendor lock-in — you own the stack.

Want this exact stack deployed and managed inside your network?
Book Your Free 30-Minute AI Audit
Service 02 · RAG in a Box

Retrieval-Augmented Generation (RAG) & Enterprise Search

Try it above — live, right now. Ask about the preloaded sample handbook (or upload a document of your own) and get an answer cited to the source. In production, this runs on your hardware against your documents — handbooks, briefs, charts, contracts, EHR notes — scoped by role.

Live demo — Qwen-3B + local vector search on an open-source stack. In production your documents never leave the building.

Workplace Use Cases

  • HR & Ops — instant policy, SOP and handbook lookups
  • Legal — precedent and discovery search across your matters
  • Medical — policy and reference Q&A without cloud PHI
  • Real estate & engineering — lease, spec and QA knowledge search
Why on-prem RAG: air-gapped from public APIs; role-scoped access (HR files stay HR-only); zero per-token fees; answers ship with source citations your auditor can verify.

Air-gapped automation over proprietary knowledge — without exposing client, patient, or matter data to a third party. Talk to Douglas AI →

1 · How many people will use it?
2 · Primary workloads
3 · Where does it live?
4 · Ongoing support

Service 03 · AI Hardware Appliances

AI Appliances — A Product, Not a Project

Pre-built from refurbished enterprise gear, burn-in tested for 48 hours before shipping, and preloaded with models and a hardened security baseline. Configure yours above — the free audit turns that sizing into a firm quote.

Workplace Use Cases

  • Offices that want AI this quarter — not in a 6-week project
  • Branch sites that need offline AI at a single location
  • MSP partners white-labeling AI for their clients
  • Standardized AI hardware across a multi-site practice

The Four Models

  • Compact / Standard: 1–2 GPU units, $1.2k–$12k
  • Pro: multi-GPU rack unit, $12k–$25k
  • Branch/Edge: low-noise single site, fully offline
  • Every unit: 48-hour burn-in, backups, remote health dashboard
Client Value: Fixed price, fixed scope, shipped and configured — with a management subscription that includes health monitoring and model updates.

Want a quote on one of these boxes for your office?
Book Your Free 30-Minute AI Audit

    Service 04 · Local AI Workflow & Automation

    Local AI Workflow & Automation — Watch the Pipeline

    Run one of three real business workflows through the automation engine. Note what matters most: every AI action is logged, and nothing client-facing is sent until a person approves it — retries, dead-letter queues, and alerts included. No silent breakage.

    Workplace Use Cases

    • Intake email summarization & CRM routing
    • Invoice parsing matched to POs; 3-way match on file
    • Support ticket triage with knowledge-base matches
    • Quote / proposal drafting from your price book (human approval built in)

    Technical Architecture

    • Engine: n8n (self-hosted) orchestrating open-weight LLMs
    • Model: Qwen / DeepSeek / Llama-class via Ollama / vLLM
    • Safety: retries, dead-letter queues, alerts — human-in-the-loop by default
    • Security: On-premises, zero data egress, every action logged
    Client Value: The repetitive work that eats a front office's day runs itself — supervised, logged, and entirely on your infrastructure.

    Have a workflow you'd like to see automated?
    Book Your Free 30-Minute AI Audit

    Beyond the Core Four

    More capabilities we can deploy

    The same on-premises pattern applied to other open-weight models. Hosted samples below so you can try the capabilities before you buy the hardware — in production, they run on your own GPUs.

    Hosted Sample · Document Intelligence

    Document Analysis & OCR

    Vision-language models turn scanned paperwork, receipts, and handwritten notes into searchable digital data. In production: local VLM, zero egress. Try the live OCR demo above — upload an image or PDF.

    Hosted Sample · Agentic Research

    Deep Research & Report Generation

    Multi-step agentic research that compiles structured, cited executive reports. The same pattern runs against your internal documents on-premises. Enter any topic above to generate a report.

    Hosted Sample · Multimodal Generation

    Image, Video & 3D Generation

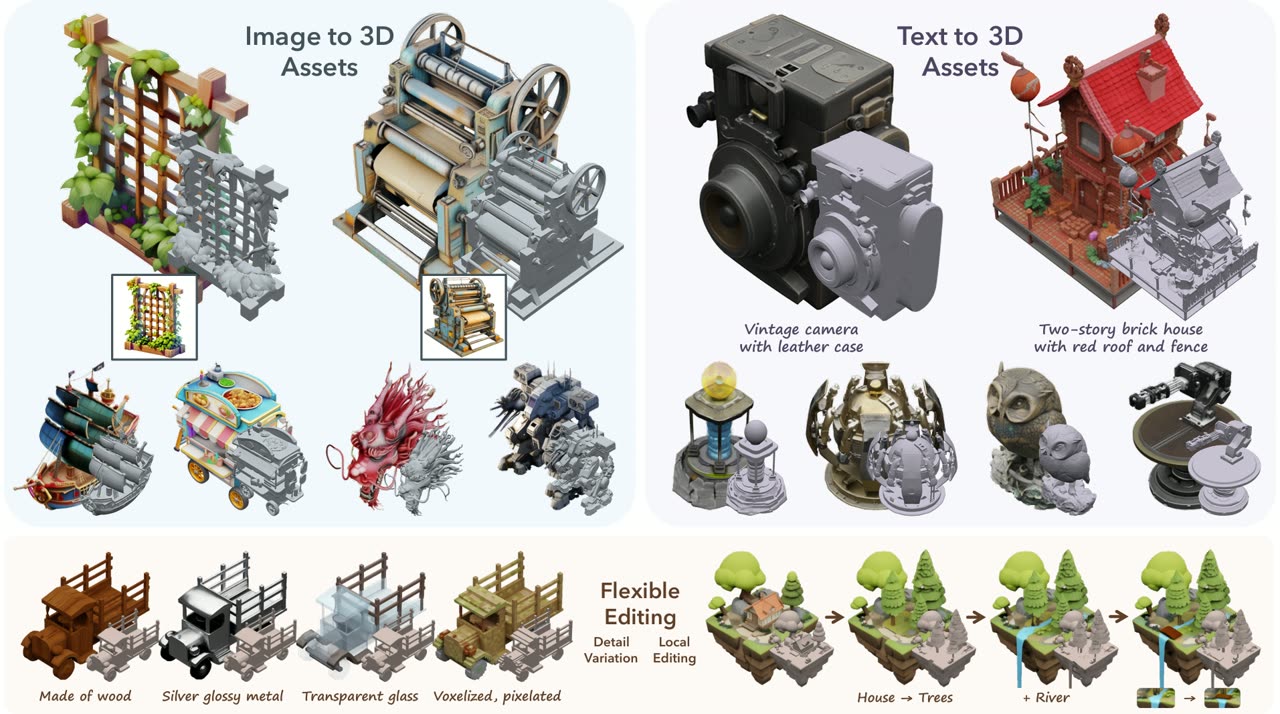
    Open-weight generative models produce HD images, short video with native sound, and 3D assets. In production: FLUX / Stable Diffusion class models on your GPUs.

    The On-Premises Difference

    Why local execution beats cloud APIs

    In production, every capability above runs on local GPUs in your network — no data to public clouds. The hosted samples on this page exist so you can try the capabilities before you buy the hardware.

    Zero Data Egress

    Firewall rules block outbound model calls. We verify with log audits and document it for your compliance file.

    No Per-Token Fees

    On-premises AI is a predictable fixed cost — owned, not rented. No surprise bills from API usage.

    Compliance Ready

    HIPAA, attorney-client privilege, GLBA — your data never leaves your control, so compliance is simpler.

    Full Audit Trails

    AI model decision logs and user activity logs — your defense and your compliance evidence.

    Ready to bring these capabilities to your team's hardware?

    Get your free AI security audit

    30 minutes. A 2-page findings memo. Zero obligation. We'll map where on-premises AI would create the most value for your practice.